 Metavershche and AIshche
Open Weights of Inkling 2 Small Multimodal Model by Thinking
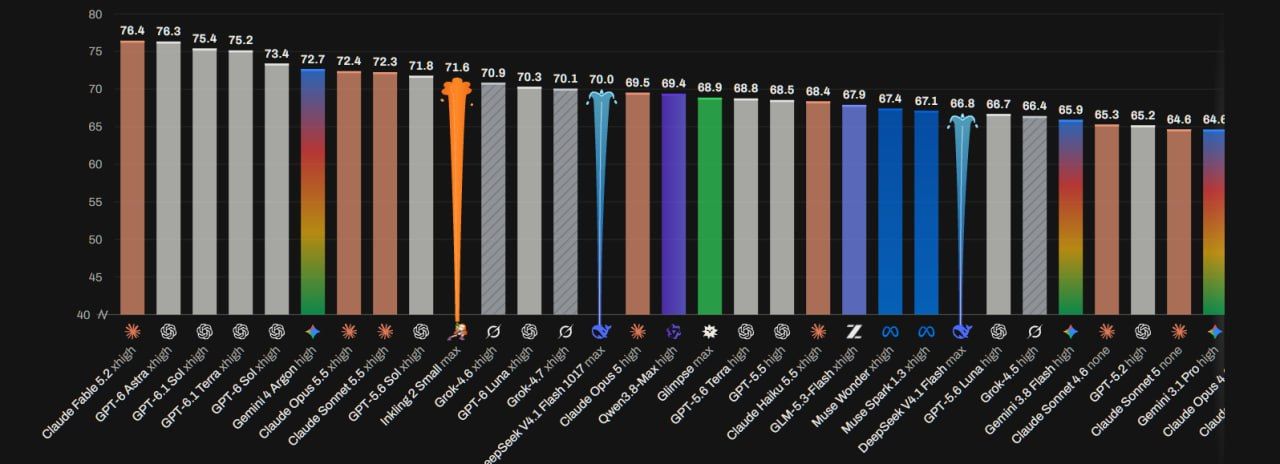
Thinking Machines Lab has released the open weights of the Inkling 2 Small multimodal model with a Mixture-of-Experts architecture under the Apache 2.0 license.
Architecture Technical Specifications
The model is a 48-layer decoder-only transformer with 594 billion parameters, activating 17 billion per token. The architecture uses routing among 8 out of 384 experts and combines local and global attention to process contexts up to 1 million tokens.
An integrated ViT encoder projects images ranging from 40px to 4096px into a shared hidden space with text. Training was conducted natively in the low-bit NVFP4 format, making this checkpoint the primary solution.
System Requirements and Deployment
Running the main NVFP4 checkpoint requires a total of at least 500 GB of VRAM, for example, on 2x NVIDIA B300 or 4x NVIDIA H200 configurations. The alternative MXFP8 option requires at least 800 GB of VRAM and offers only a marginal accuracy gain.
Inference is available immediately after release via ready-made recipes for vLLM (with native DSpark speculator), SGLang, TokenSpeed, and Unsloth.
For fine-tuning and API usage, Tinker Cookbook, Miles, SkyRL are supported, as well as hosting on NVIDIA, Together, Fireworks, Baseten, Nebius, Modal, and Cloudflare platforms.