 in IT and out (v IT
Kandinsky 6.0 Video: Sber's Video Generation with Sound
Sber has released Kandinsky 6.0 Video — a new line of models for generating video with synchronized audio.
The new models can create videos with dialogues, music, and background sounds. The audio track is strictly synchronized with the visual content, and characters' lip movements match their speech.
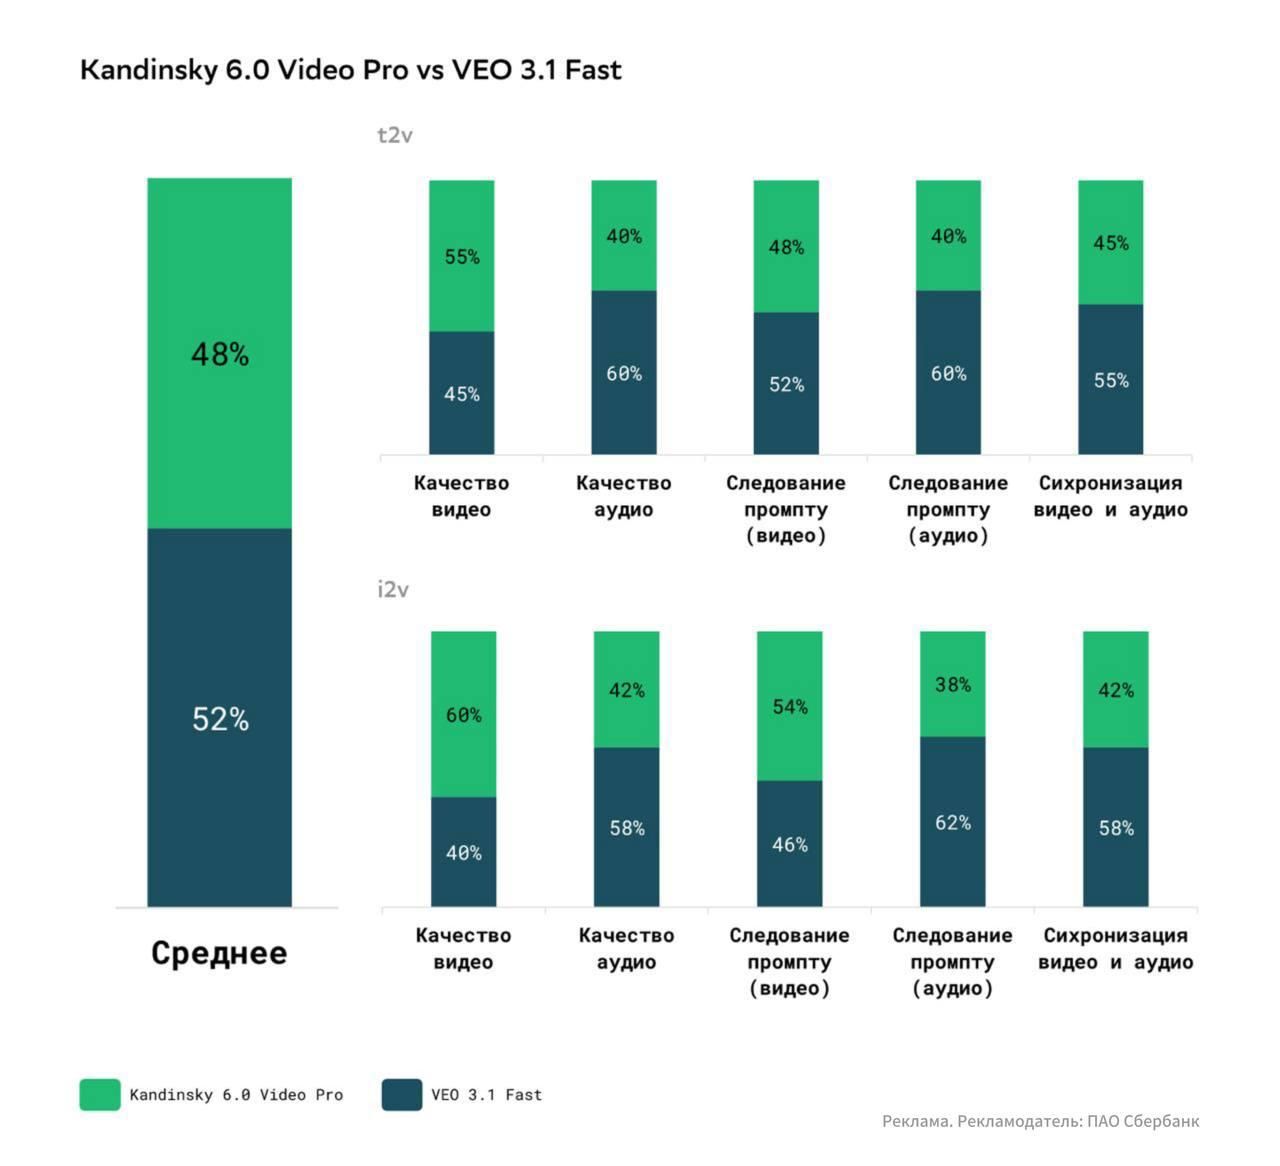
For over six months, the previous version of Kandinsky held the top spot among open text-to-video models on arena.ai, competing with Veo 3. The new flagship demonstrates results on par with Veo 3.1 Audio.
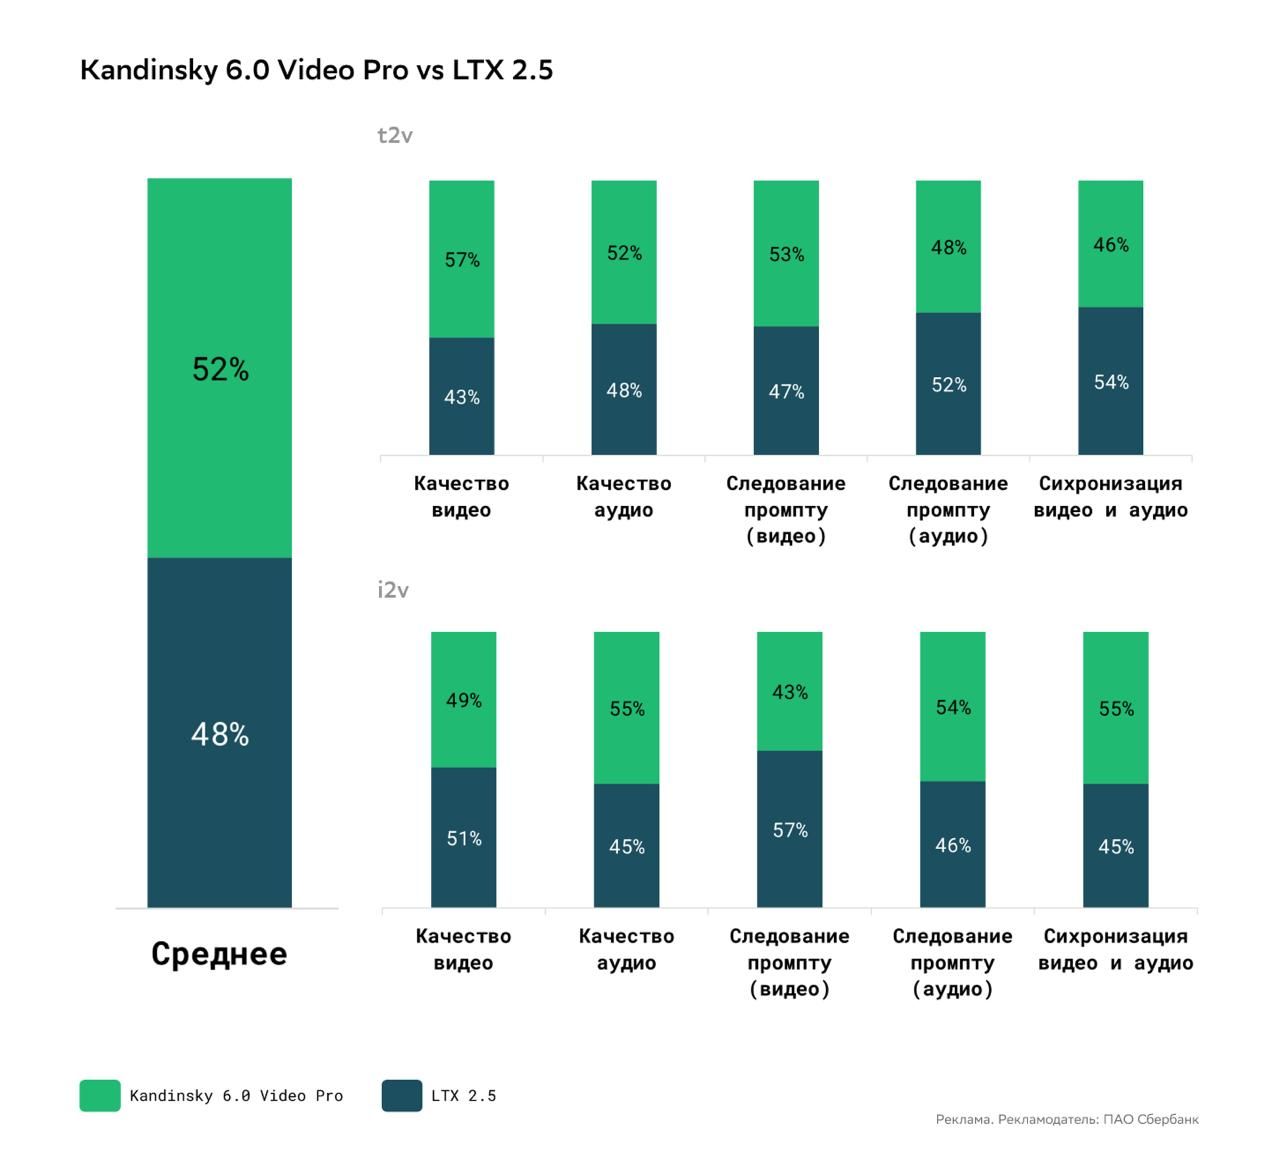
Among open models, the new release trails only MiniMax H3, achieving parity with LTX 2.5. A lightweight Lite version with 3 billion parameters is available to users.
- Model weights are available on Gitverse
- Source code published on GitHub
- Detailed technical report available
- Free testing available in GigaChat
22K views