 Metavershche and AIshche
Baidu Unveils Unlimited-OCR 2 for Long Document Recognition
Baidu has released Unlimited-OCR 2, a model for recognizing documents of any length. The new SR-SWA mechanism accelerates processing by 7 times and reduces memory costs.
Baidu Unveils Unlimited-OCR 2 for Long Document Recognition
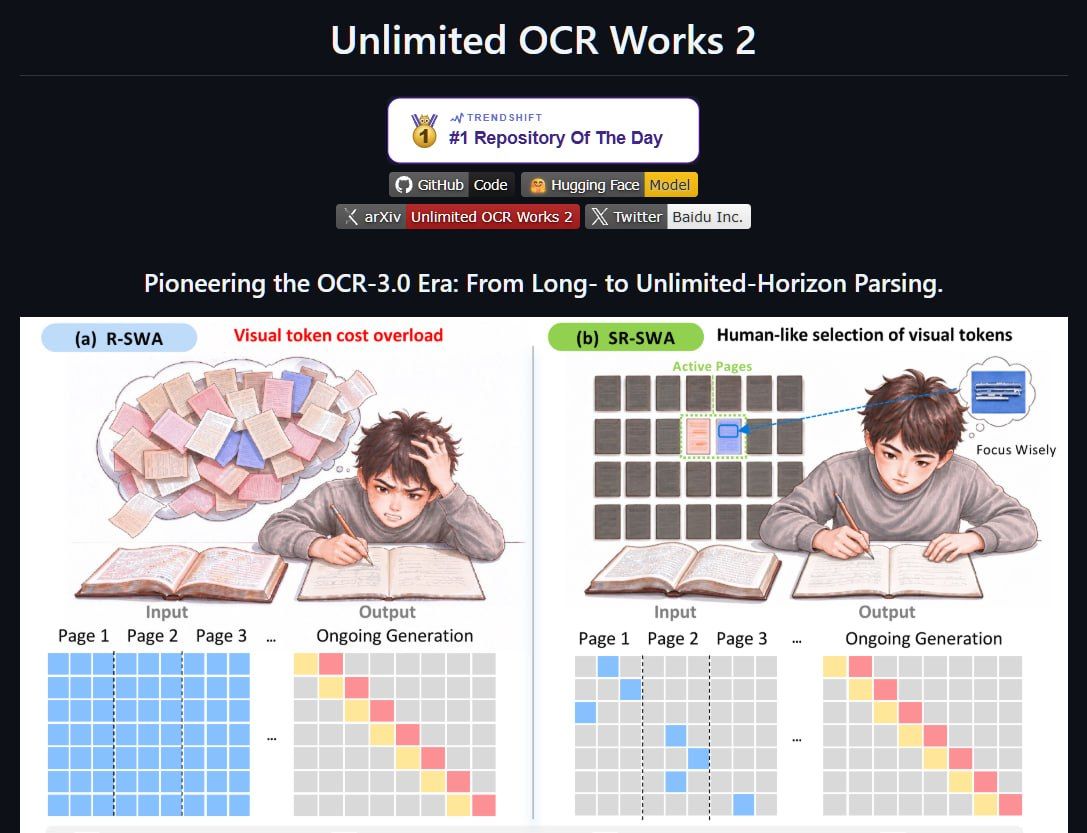
Modern LLM-based models require increasing amounts of computation and memory when processing long documents. This is due to the need to constantly access the growing volume of previous context.
The first version partially addressed the issue by limiting generation history, but visual data created a burden. Baidu proposed the Sparse Reference Sliding Window Attention (SR-SWA) mechanism to optimize the process.
How the New Mechanism Works
The idea behind the mechanism is simple: when recognizing a fragment, the model focuses on the current page and accesses only a small set of useful parts of the document. Instead of viewing all information, it uses a limited working memory.
For example, the system can use 512 reference tokens. The computational cost per step remains constant even as document length increases. Additionally, overlapping block page processing is applied to free up memory.
Testing Results and Availability
According to Baidu tests, on documents of about 100 pages, the acceleration of individual decoding steps reaches 7 times relative to full attention and 5.6 times compared to the previous mechanism. The model contains approximately 3 billion parameters.